Inference Throughput · KV Cache Architecture · Serving Frameworks
A blog and newsletter on KV cache architecture, management, and optimization and GPU inference performance and throughput engineering.
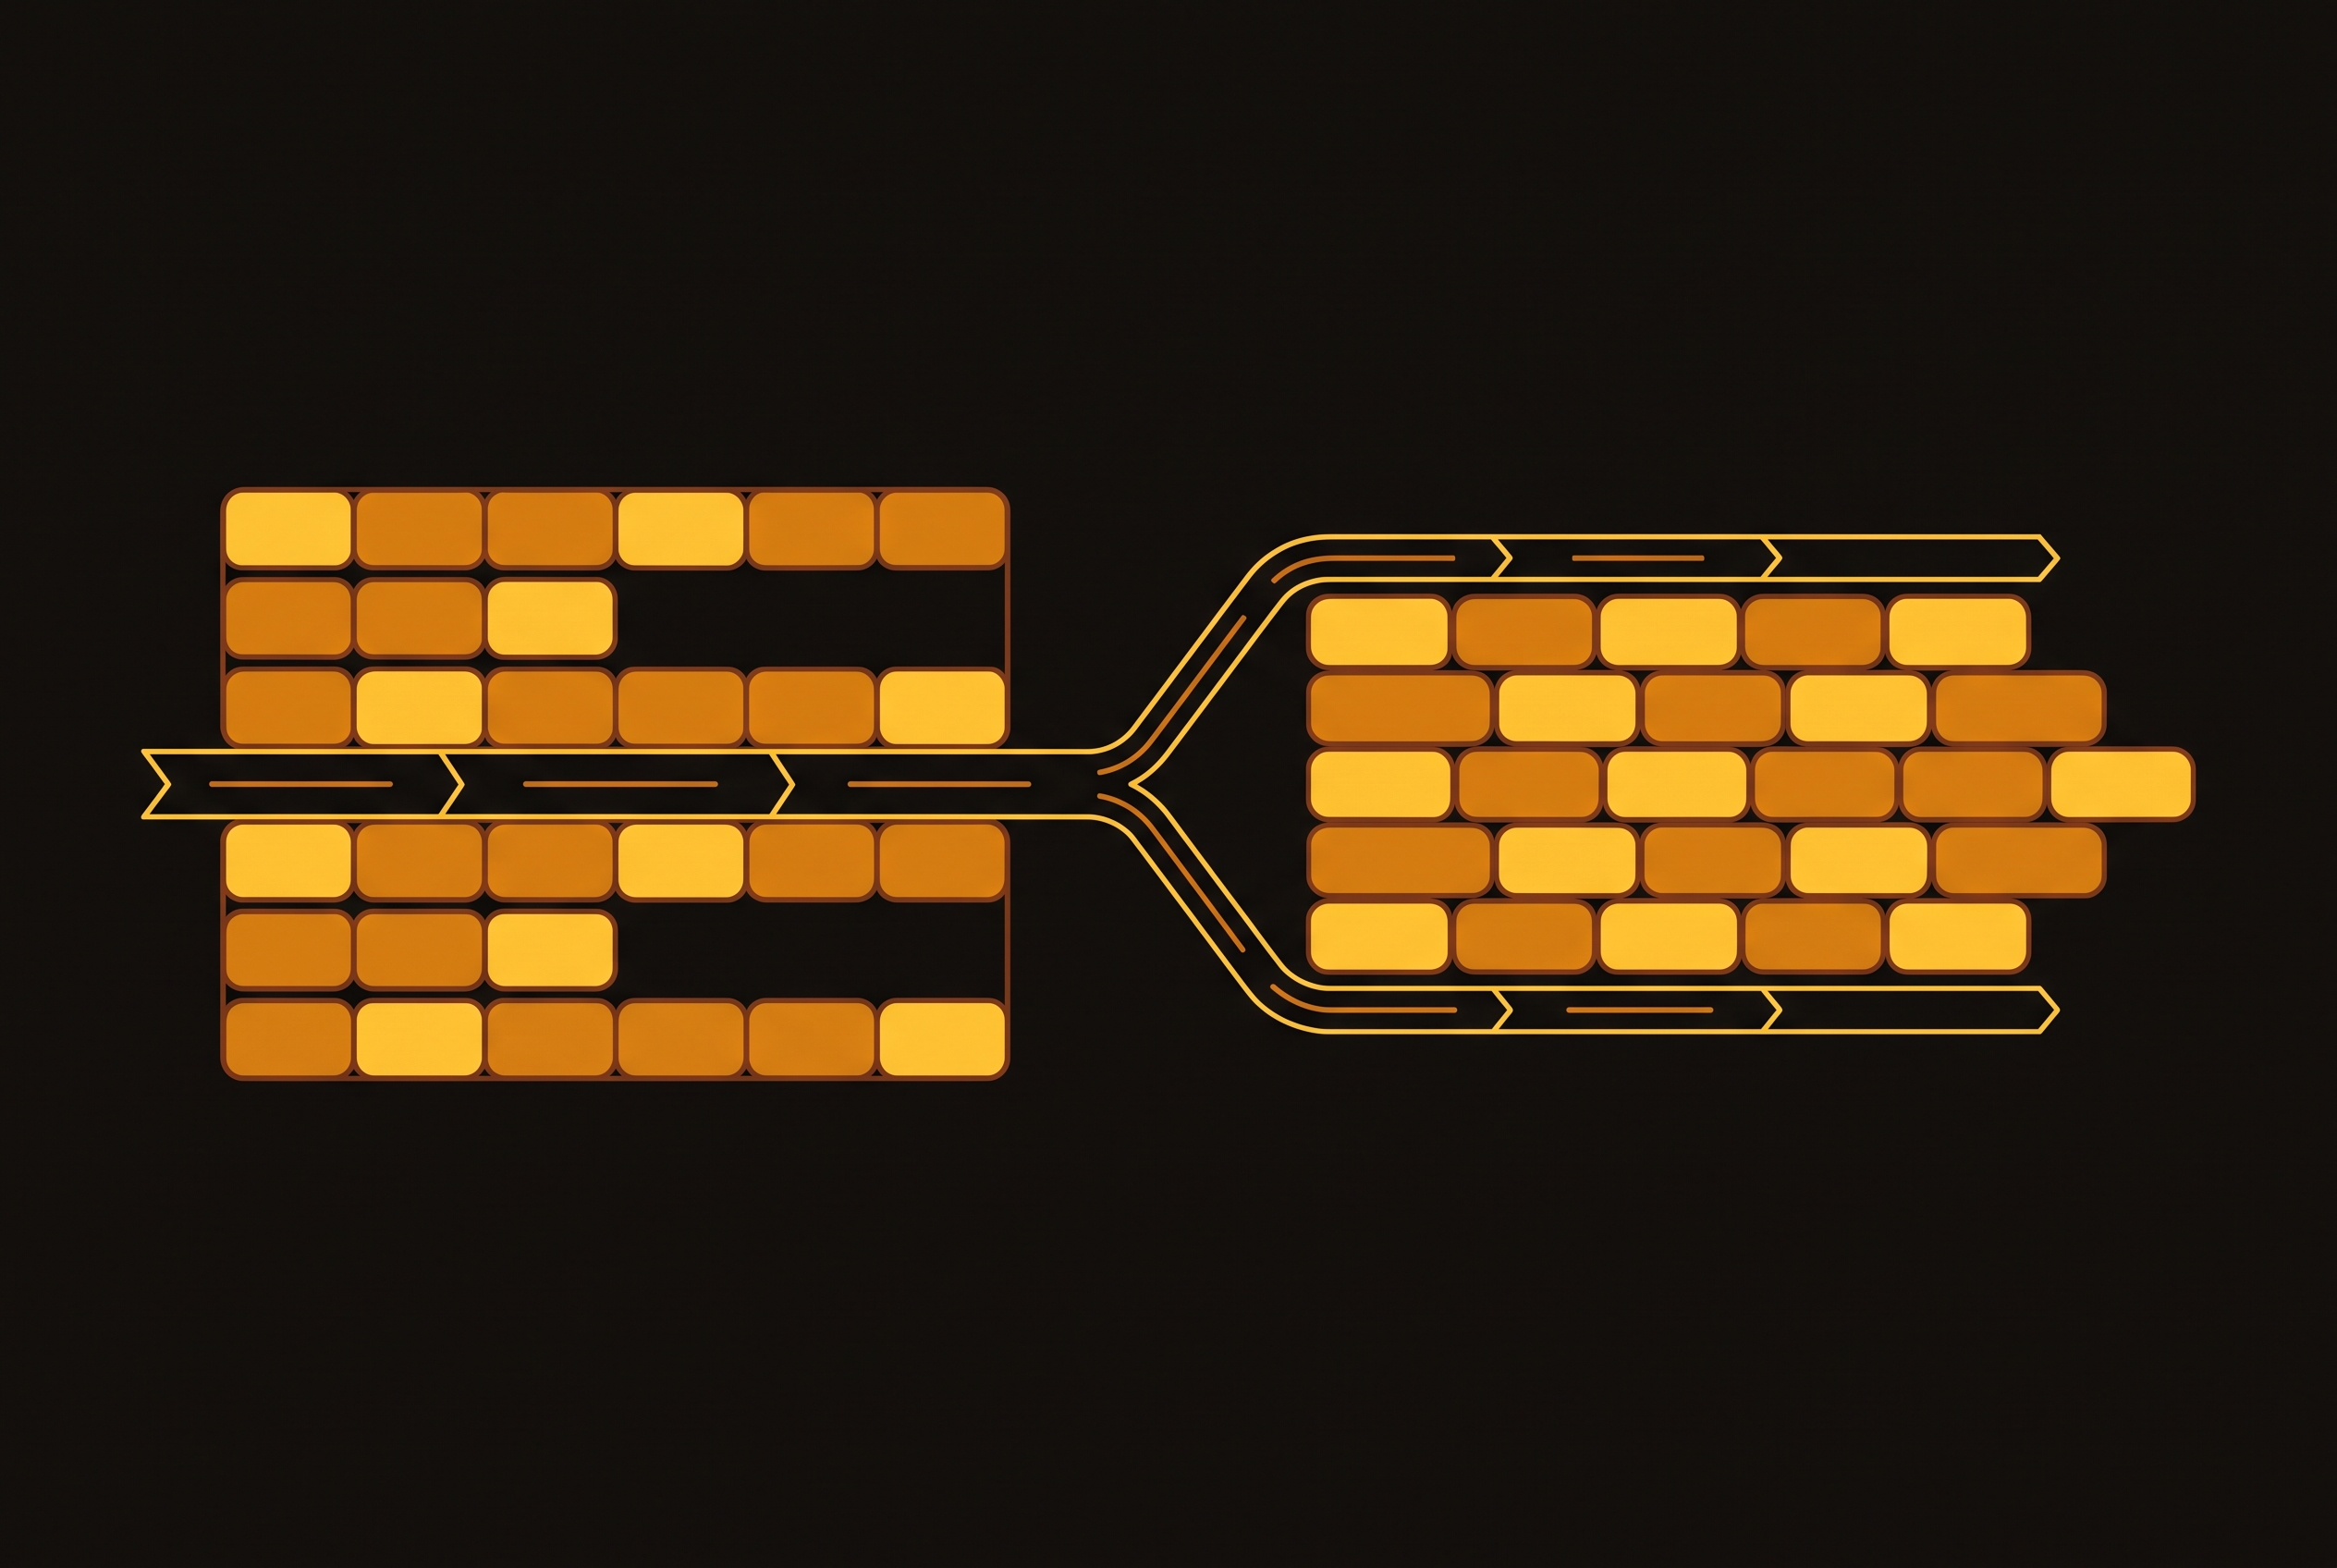
Inference Throughput
Continuous Batching vs. Static Batching in LLM Serving
Continuous batching keeps GPU slots filled while static methods leave them idle.
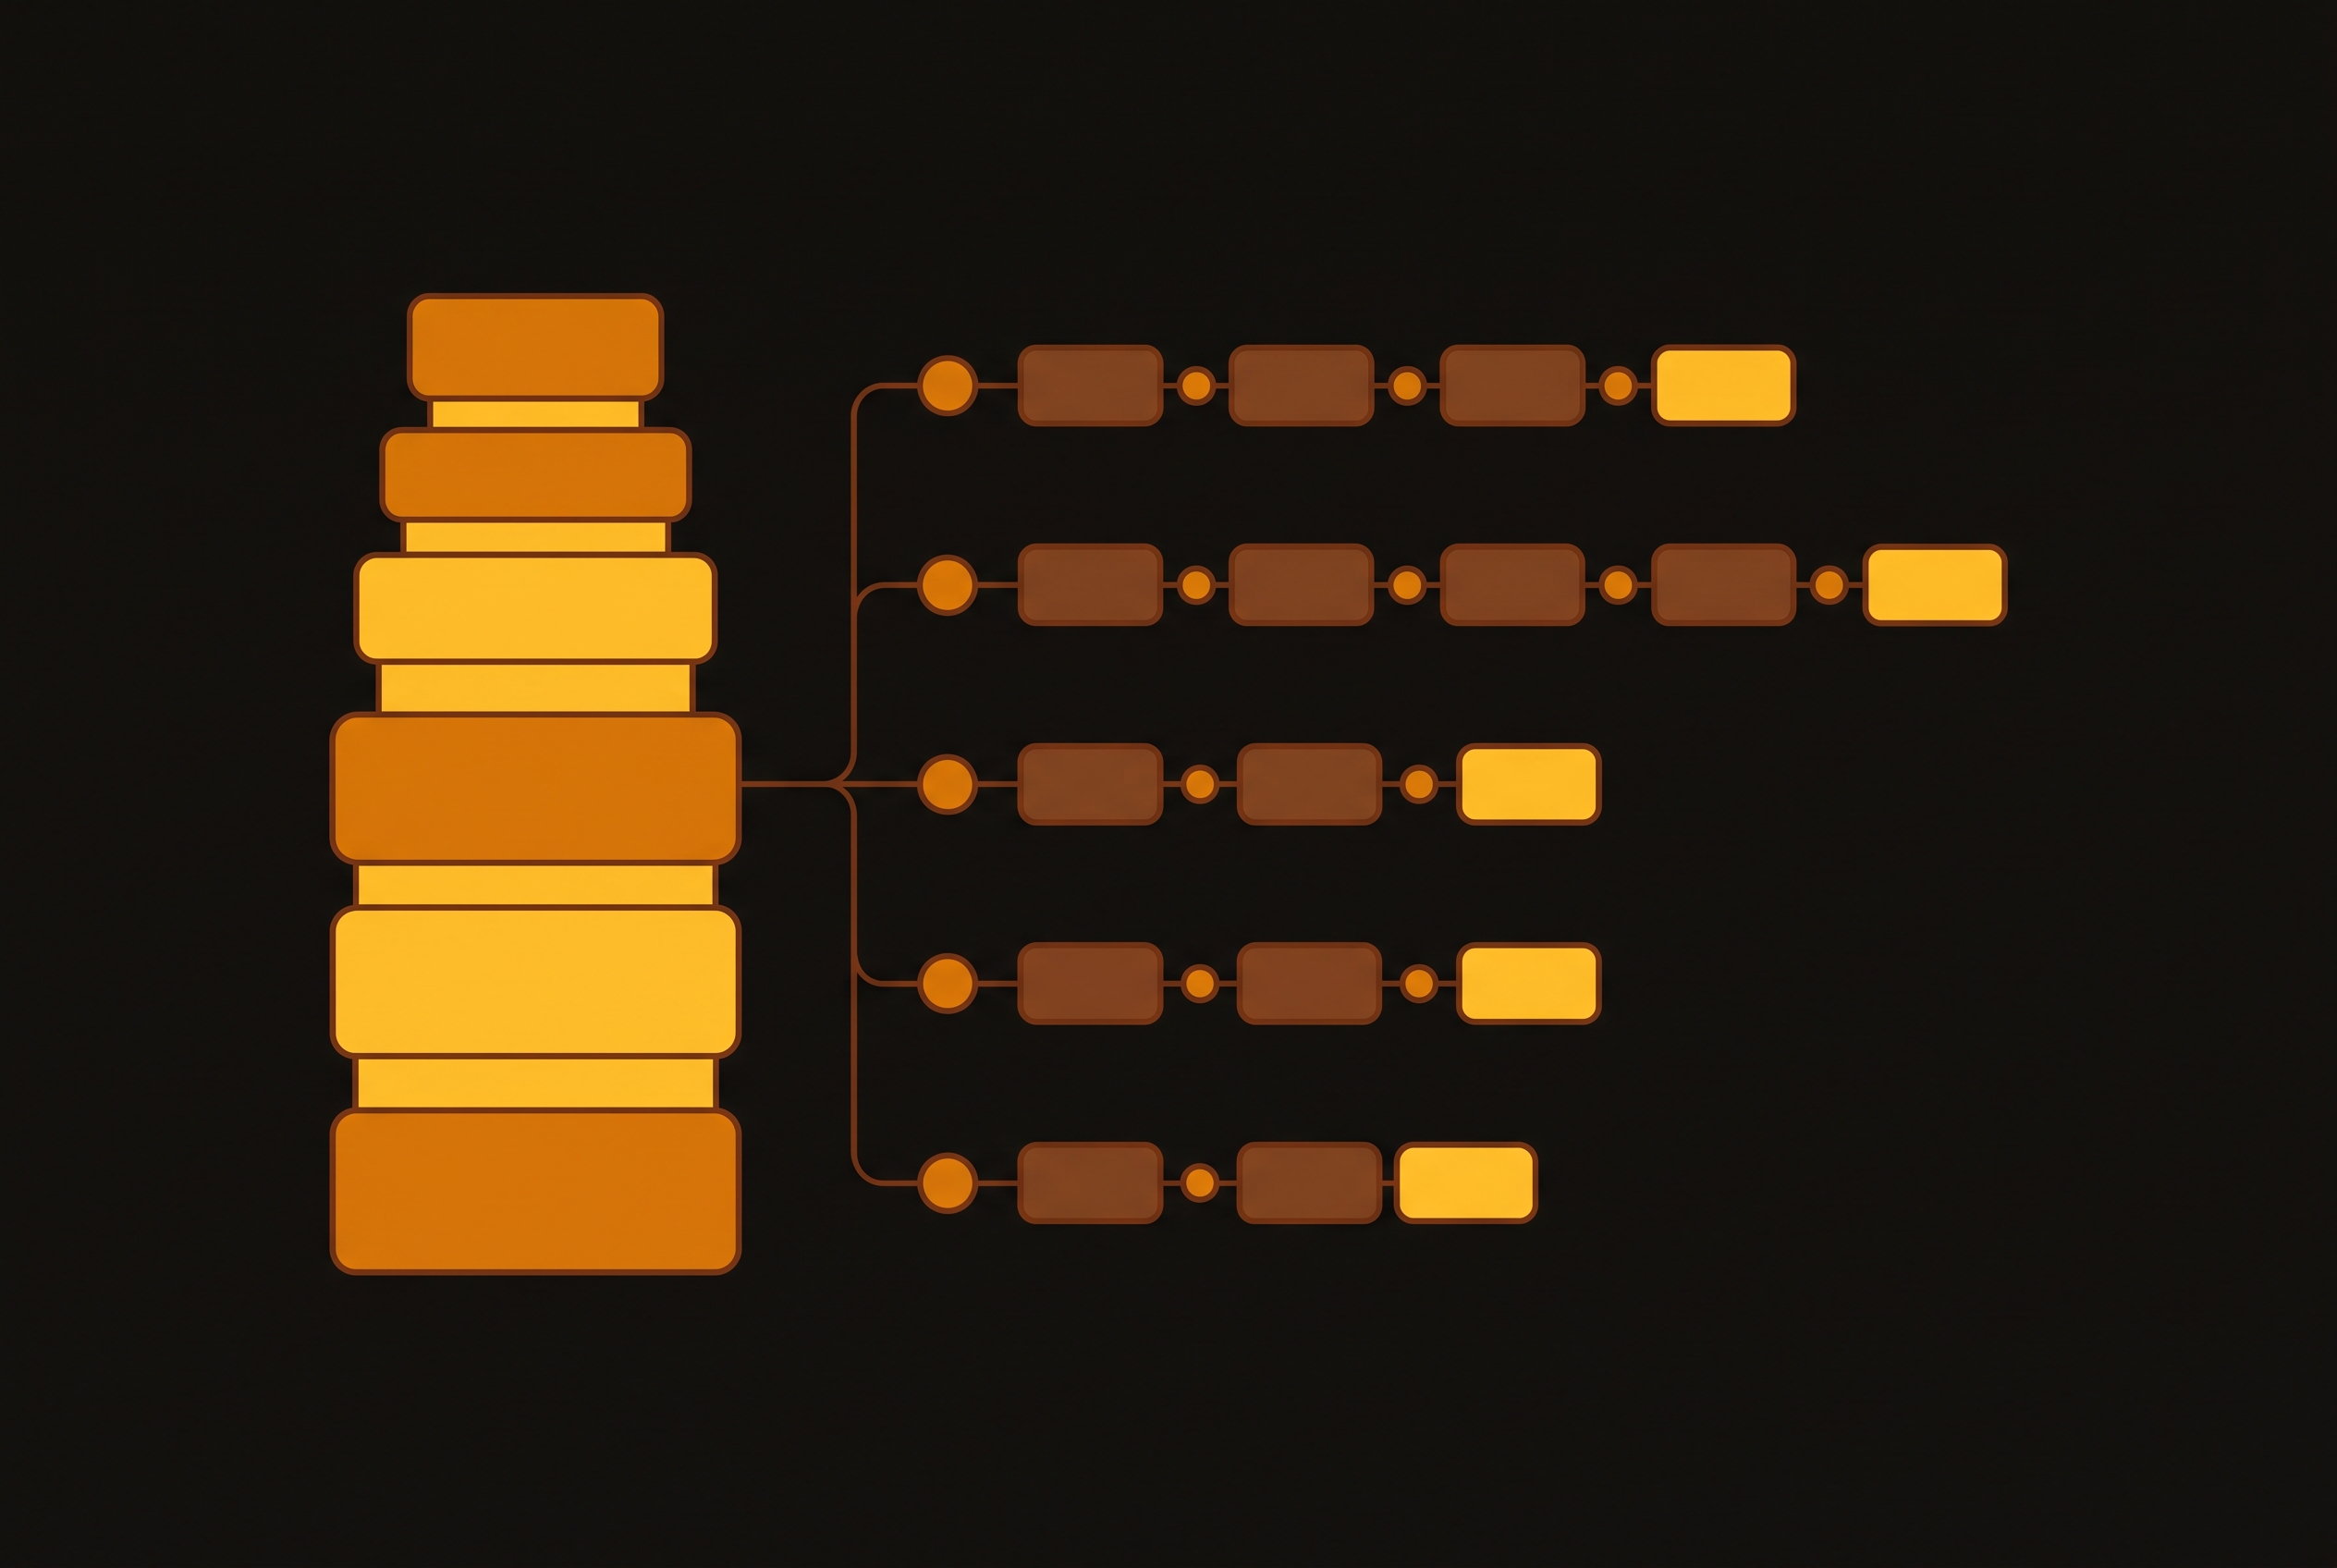
KV Cache Architecture
Prefix Caching for Shared System Prompts
Serving Frameworks